
Built for every industry. Trusted by global brands bringing privacy, performance, and intelligence to the edge.
Contact Us

A serial entrepreneur with an IPO, an acquisition, 50+ patents, and a lifetime in audio-tech innovation. Todd has deep experience licensing and working with the largest tech companies in the world, including Amazon, Apple, Google, Microsoft, Samsung, and many others.
See how Sensory technology transforms user experiences — instantly, privately, and securely.


Wearables have a fundamental challenge: batteries have finite power and require careful resource management to provide a persistent hands-free voice interface without requiring a physical trigger. If always-on voice services drain too much power, the feature gets turned off, delayed, or removed, which limits its usability.
For consumer electronics manufacturers, the challenge is not whether voice can work on a wearable. It is whether voice can stay on all day, in real-world conditions, without hurting battery performance or responsiveness.
Battery life is the gatekeeper for wearable voice features. Smartwatches, hearables, and smart glasses already run lean, but powerful processors, so every extra background task – including microphones, sensors, radios, and display logic – compete for resources.
That is why always-on voice is sometimes treated as a luxury feature instead of a core interaction mode. But when it is implemented with ultra-low power, multi-stage architectures on-device, wake words and voice commands can become a small part of the power budget. Sensory’s wearable solutions are built for exactly that kind of deployment.
Ultra-low power voice AI is not just “efficient.” It is designed to keep listening active at the lowest practical energy cost, often in the microamp range for voice activity and wake detection. Once a wake word is detected, a larger processor can be fired up in short bursts for heavier command and speech-to-text processing.
In simple terms, the goal is to avoid waking the full processor stack until the device actually needs to respond. That is where accurate keyword spotting and compact on-device models matter. Sensory’s wake word technology is designed for minimal CPU usage and can run on constrained hardware, including devices with very limited RAM and power headroom. And Sensory’s more capable AI models are designed to run efficiently on device by taking advantage of both CPU accelerators and NPUs when they are available. This ensures that power consumption is optimized across all of available resources.
For some products, energy harvesting may require limiting processing on device and extending some of the runtime processes to the cloud. For most wearables, the practical answer is smarter hybrid architecture: low-power wake detection, on-device speech-to-text when needed, and cloud for tasks that truly benefit from more compute, real time or large quantities of data, and sophisticated applications – including LLMs, shared business systems, and third party applications. Sensory’s hybrid approach supports that model by keeping processing local first and sending only lightweight text to the cloud for further application processing as needed.
Cloud-only voice adds battery overhead in three places: always-on listening, high bandwidth wireless transmission, and round-trip latency. On a wrist-worn or body-worn device, that overhead adds up fast.
Local processing solves more than battery life. It also improves privacy and reliability by keeping voice, sound, and biometric data on the device unless the experience explicitly requires cloud handoff. Developers can also segregate on-device command and control functions to work without any network connectivity, resulting in faster response time than a cloud service round trip. Sensory’s wearable stack is built for this local-first voice and application management, which is why it works well for compact products that need fast response without the overhead of persistent streaming.
Sensory brings multiple on-device AI capabilities together for wearables:
This combination of technologies working together matters because different voice tasks have different power and use case requirements. It begins with accurate wake words that listen on extremely low power all the time and accurate enough to avoid falsely firing up other resources unnecessarily. Command sets and speech-to-text need to be compact and accurate enough to run locally and have the intelligence to escalate to cloud services only when needed. Biometrics can overlay any speech component to add personalization and security without adding noticeable delay for friction. Sensory’s software stack is designed for flexibility and optimization on any wearables platform instead of forcing a cloud-first model onto a battery-constrained device.
Before shipping always-on voice in a wearable, product teams should pressure-test five questions:
If those answers are not clear, there may well be a mismatch between the components and the real world user experience. Sensory helps OEMs avoid that outcome by helping design the optimal user experience on the available resources.
For wearables, the best voice experience is typically not wake word to cloud-only. It is an ultra-low power on-device AI stack with selective cloud connectivity.That is the approach Sensory brings to wearables, hearables, and smart glasses: fast wake words, compact speech recognition, sound awareness, and biometric security that fit into power-constrained products. If your team is planning a keyboard-free, wearable voice feature, contact our team or read the Jabra case study to see how others have been successful.
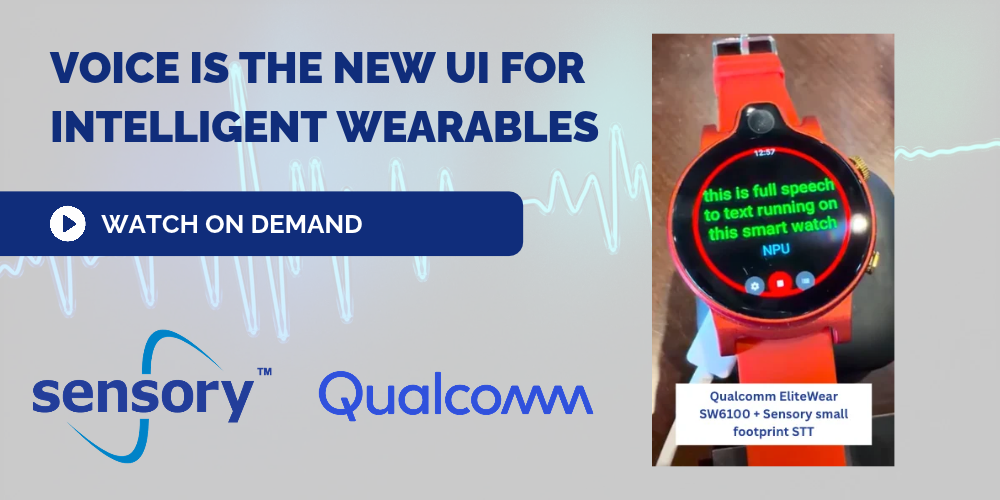
Watches, glasses, pins and pendants are getting smarter and smaller at the same time. With little or...
 Todd Mozer
Smartwatches and smart glasses are forcing a simple truth: on a 40mm screen, voice is not a nice-to-have....
 Todd Mozer
The design philosophy for intelligent hearables—earbuds, hearing aids, and smart glasses—is undergoing...


